Agents & Efficient Reasoning
2025–present
My work across six research directions. Each flower represents a paper; the stems group related topics, with recent work toward the top.
2025–present
2023–present
2021–present
2024–present
2022–present
2021–2023
Newer papers appear toward the top of each stem. The full descriptions and paper lists follow below.
2025–present
At Apple, my current focus is efficient on-device tool-calling agents and reasoning compression. My public work studies how agents learn from feedback, reason over evidence, and act in unfamiliar environments. MAGNET (NeurIPS 2025) coordinates agents across multiple videos. In 2026, Simulate to Generalize scales stateful API-calling supervision with LLM world models; RLTL;DR internalizes self-generated insights; and MoE Expert Selection aligns expert routing with agent operations. Minimal Cores examines which reasoning steps support a prediction, while our TMLR survey maps perception, reasoning, planning, memory, and action in multimodal agents.
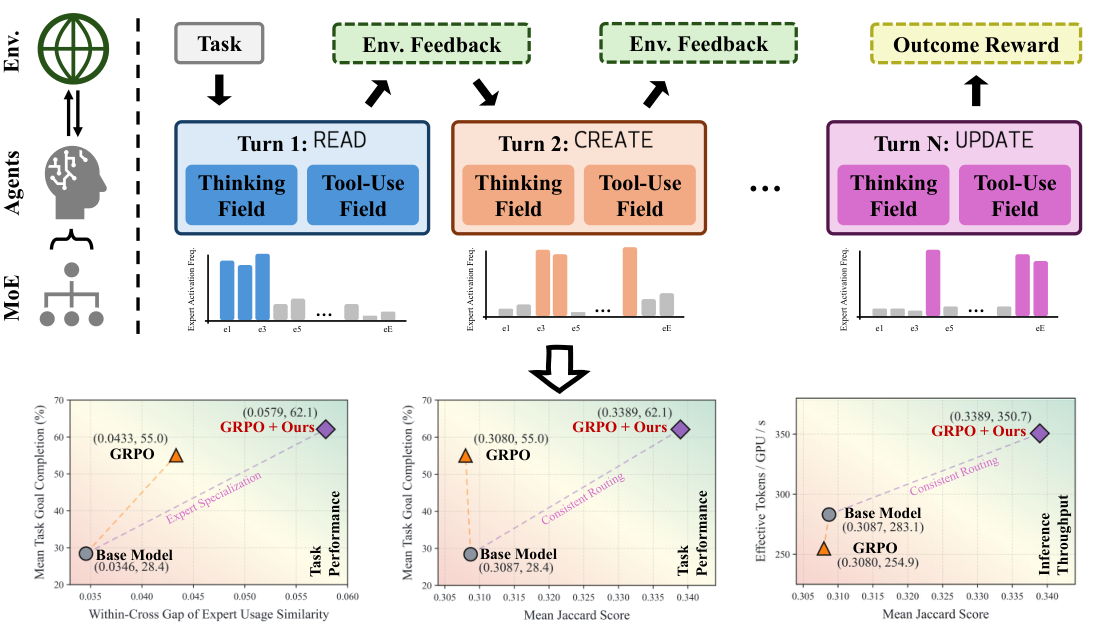
Aligning mixture-of-experts routing with agent operations through hierarchical control during reinforcement-learning post-training.
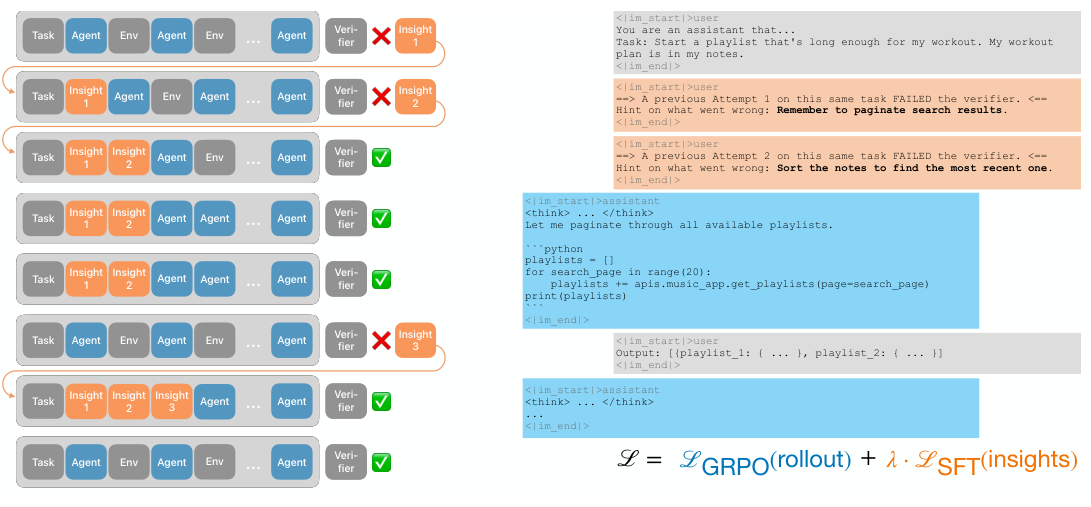
Learning from brief, self-generated insights after failed attempts, then internalizing those insights during training.
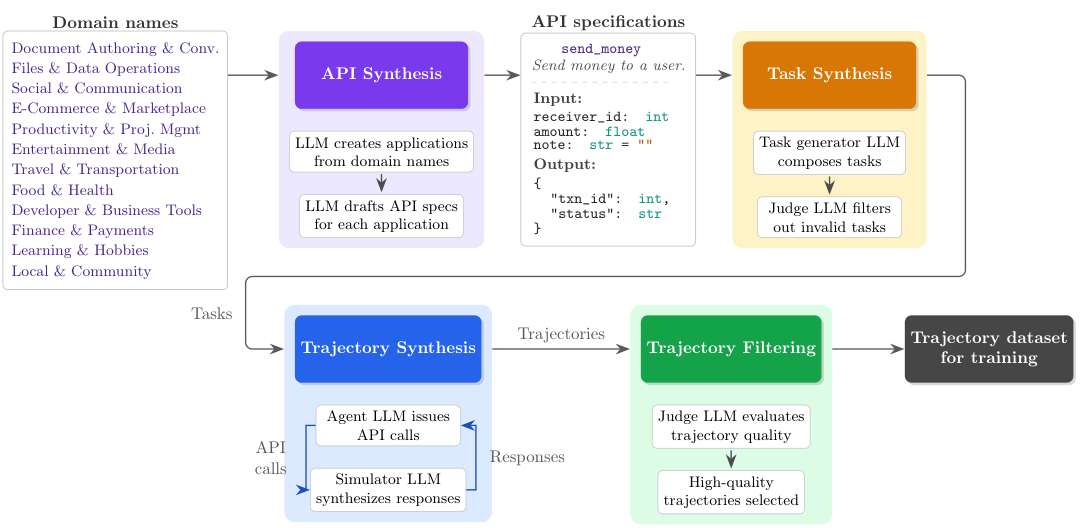
Generating stateful API-calling trajectories with LLM world models to train agents that generalize to unseen environments.
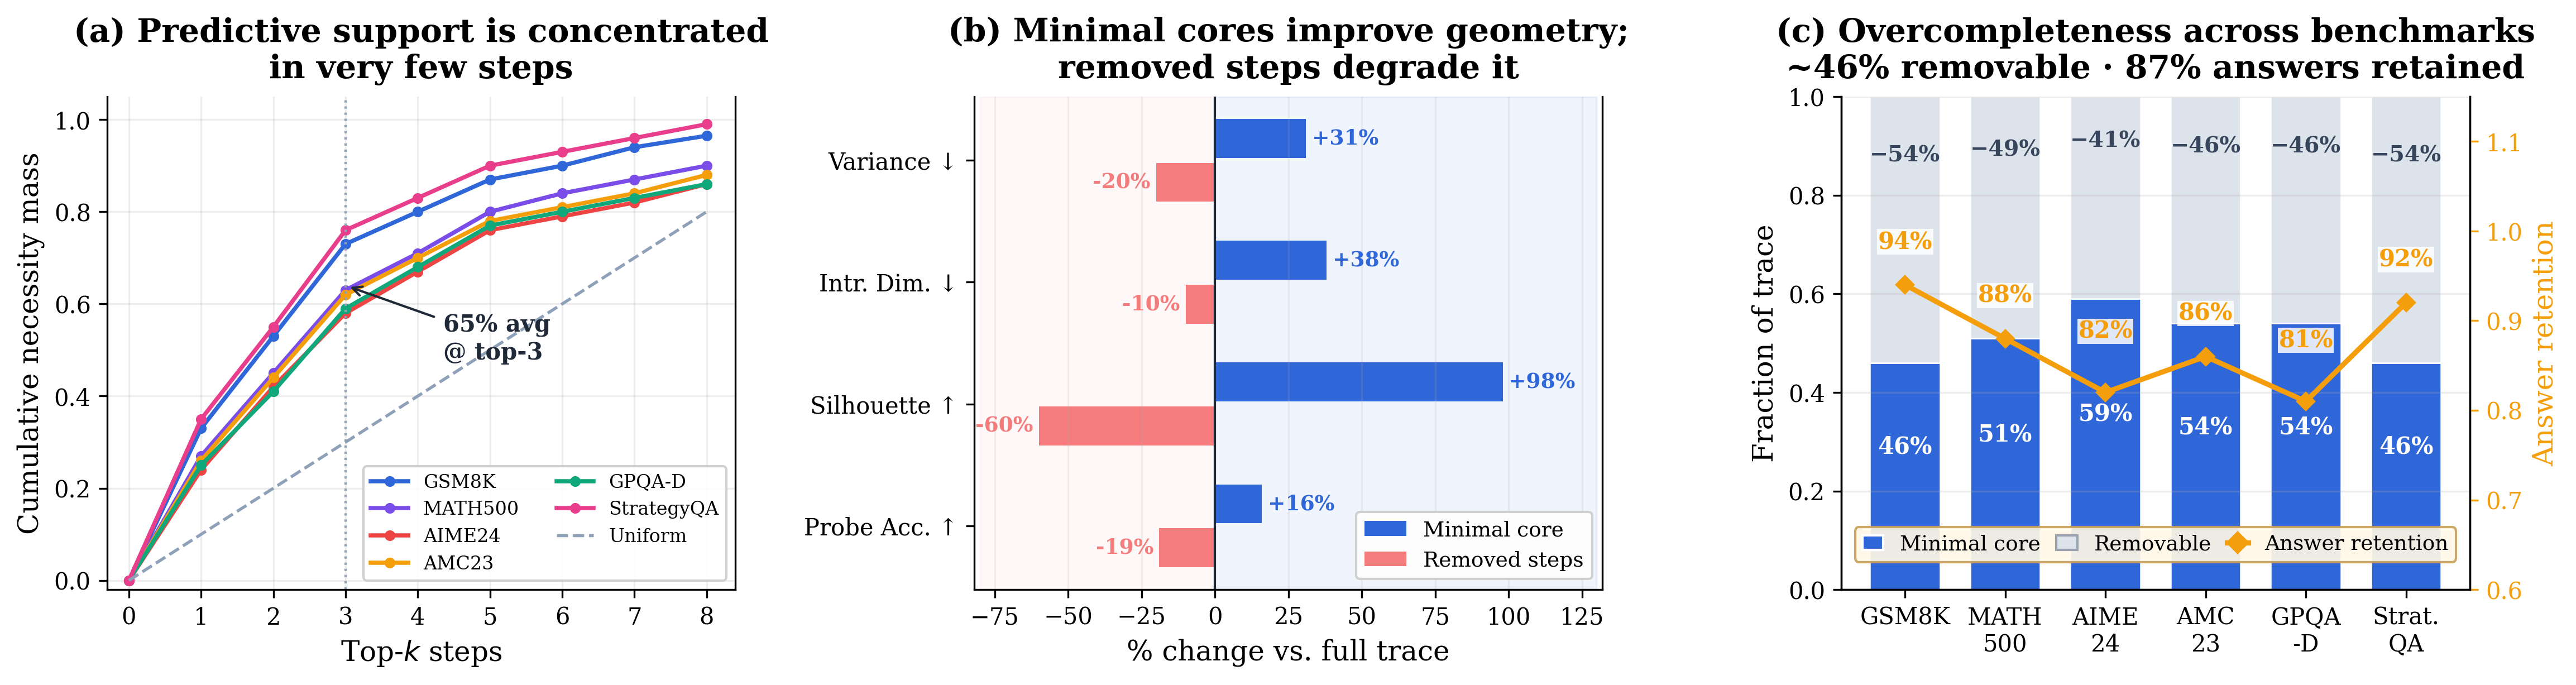
Identifying the compact support within long reasoning traces and studying its representation geometry.
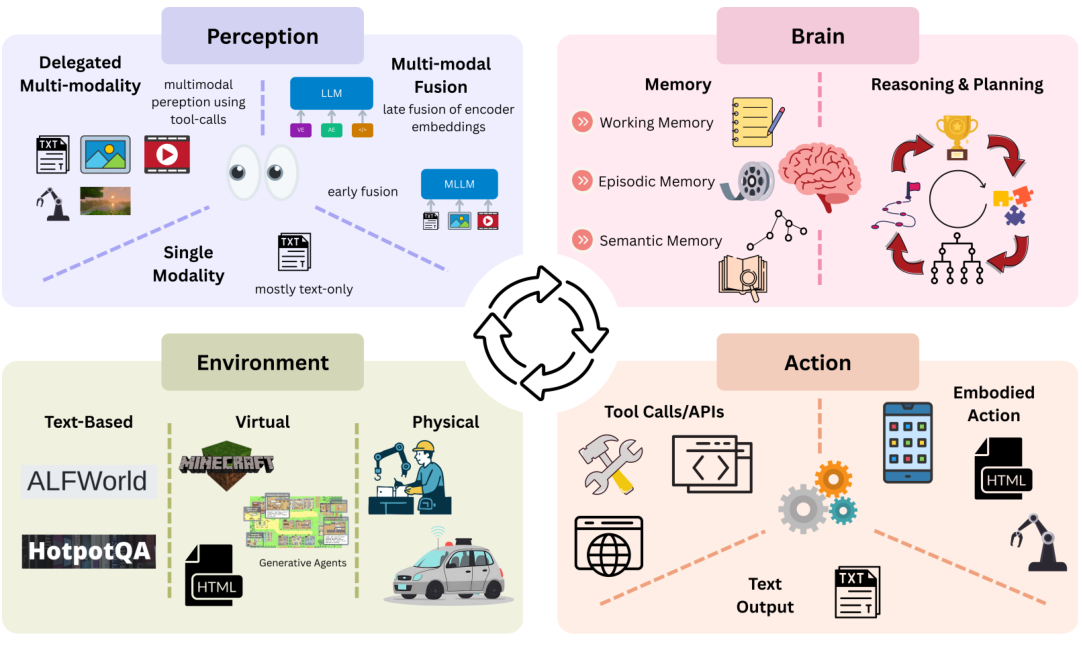
A survey of the techniques, applications, and open challenges in multimodal agentic frameworks.
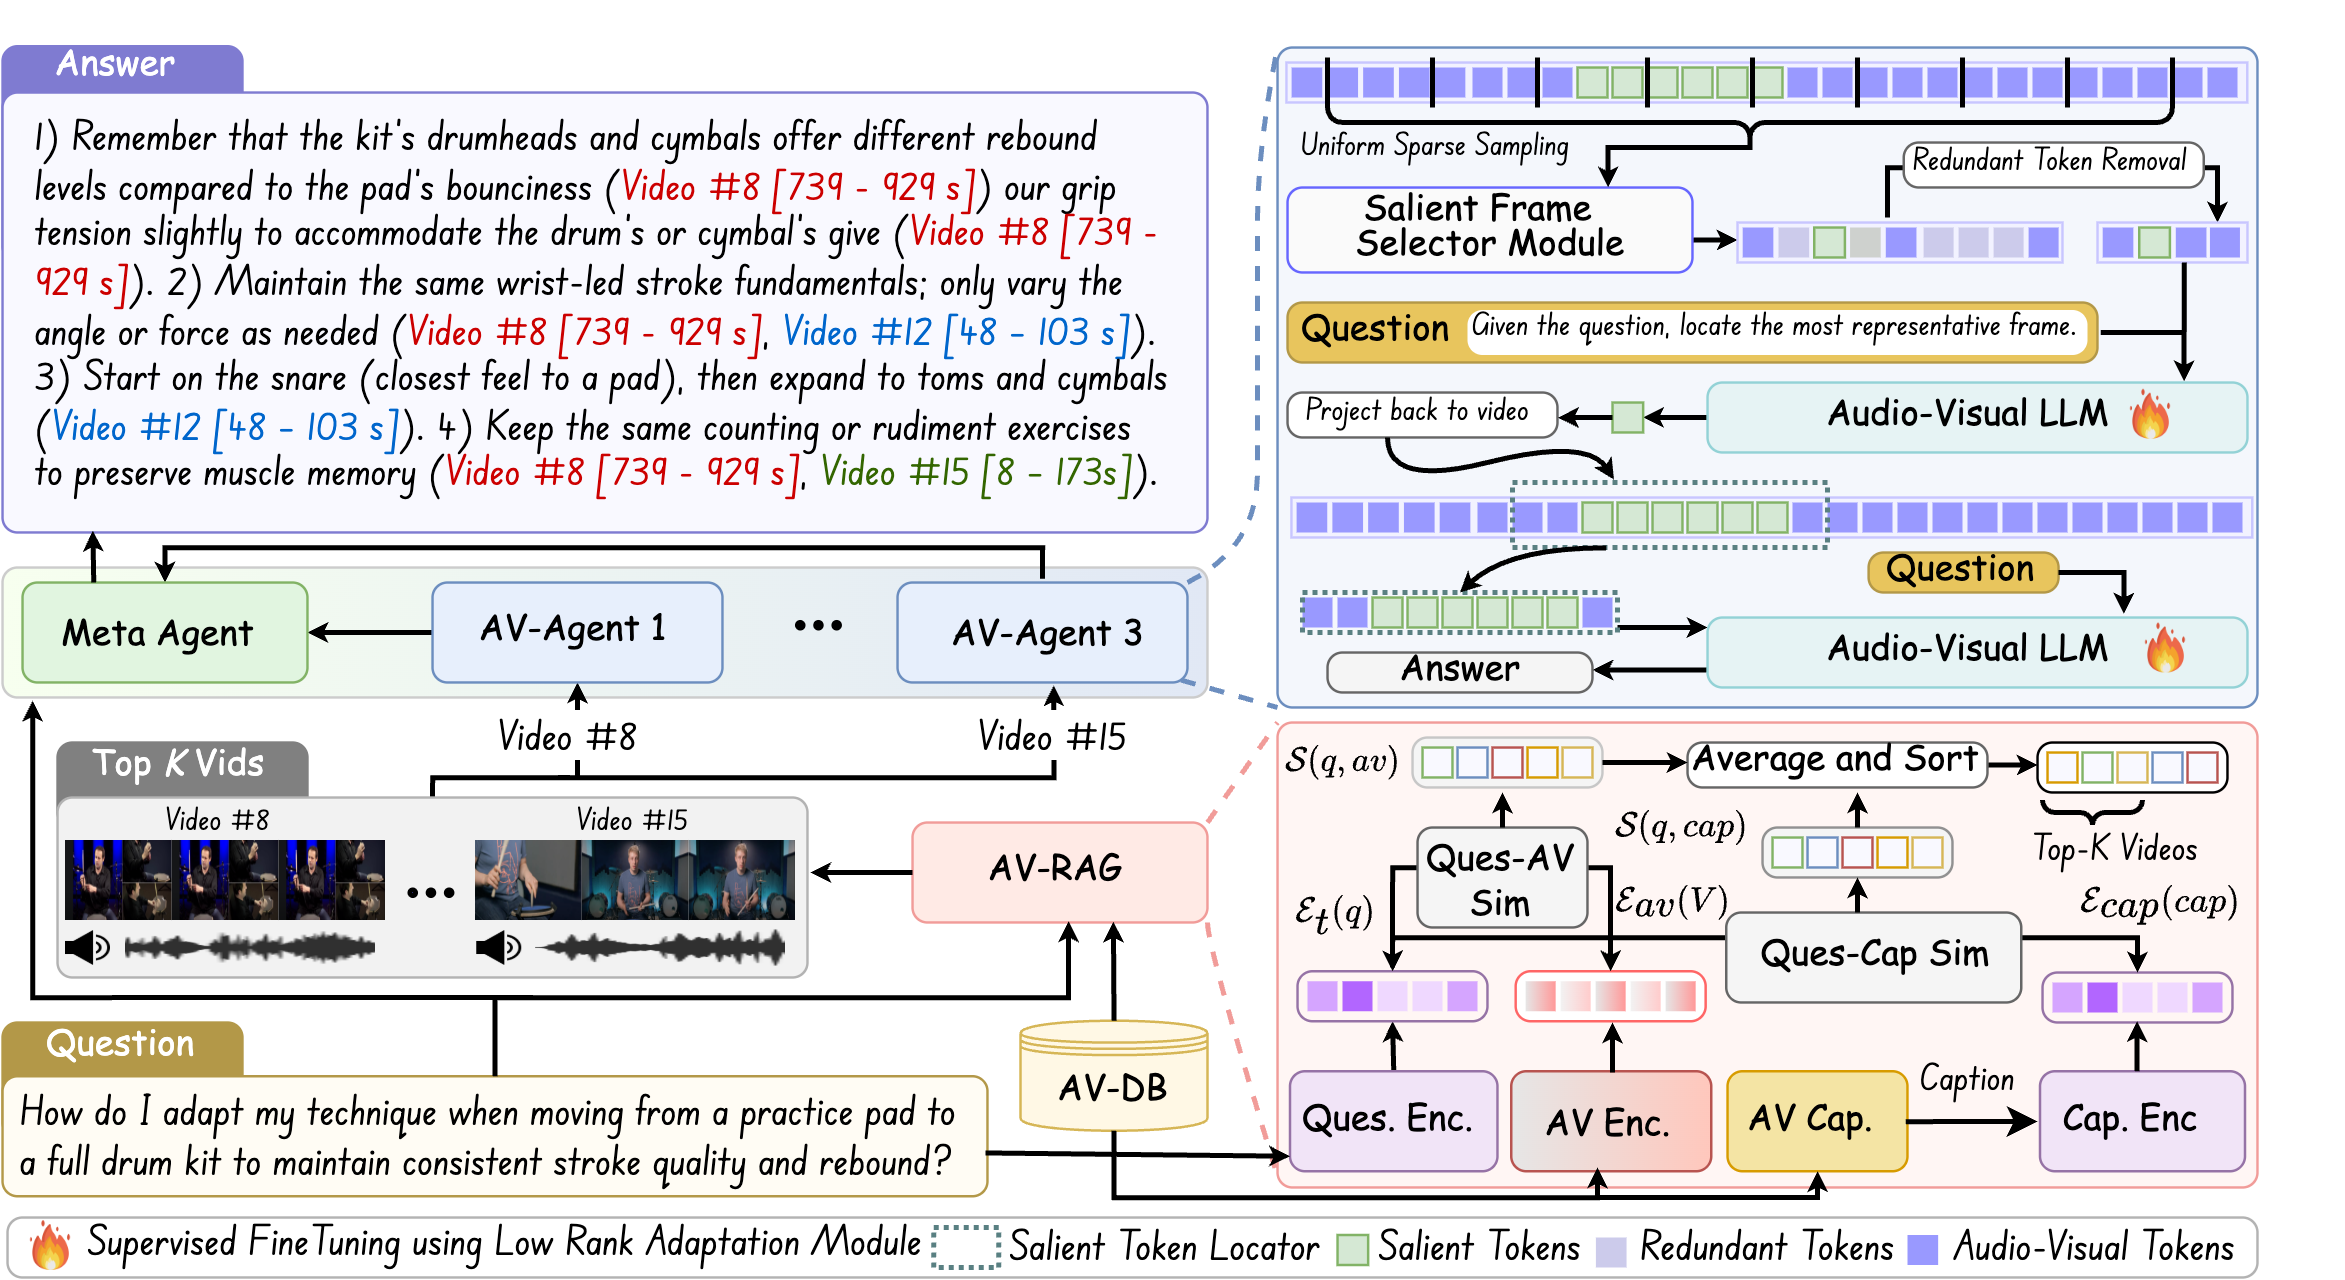
Multi-agent retrieval and reasoning over audio-visual evidence distributed across multiple videos.
2023–present
How can visual and language cues guide the generation or refinement of audio? MeLFusion (CVPR 2024, Highlight · Top 2.8%) combines images and text to synthesize music with diffusion models. AdVerb (ICCV 2023) uses visual context to estimate clean audio from reverberant recordings. Together, they study cross-modal conditioning for creative synthesis and audio restoration. More recent work, including MAGNET and AMUSE, broadens my focus to evidence-grounded multimodal reasoning and agents; those papers appear in the related directions below.
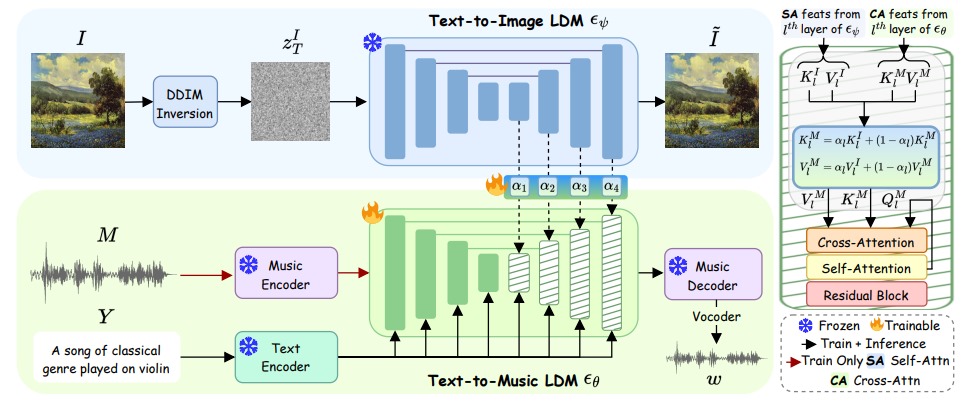
Synthesizing music from image and text cues with a diffusion model and visual synapses.
Presentations: Invited talk · Sight and Sound, CVPR 2024
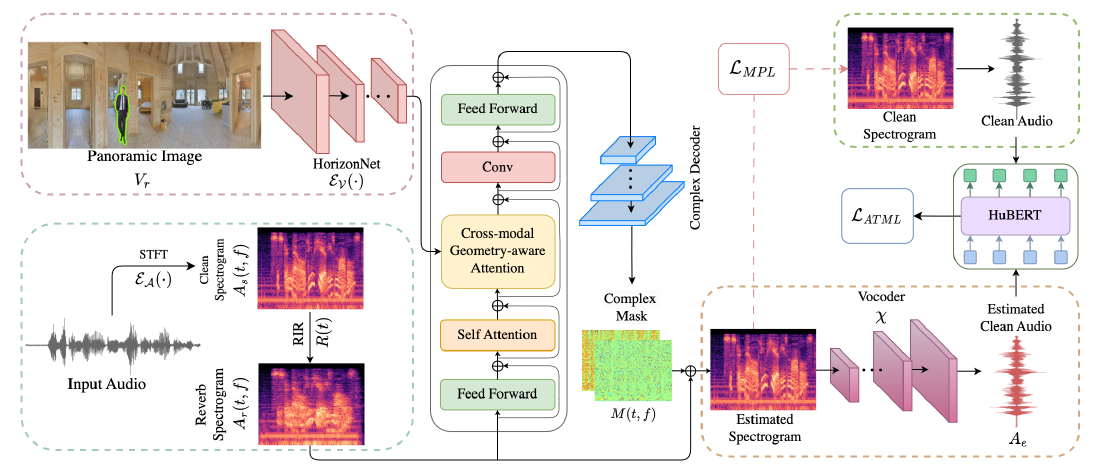
Using visual context to help estimate clean audio from reverberant recordings.
Presentations: Invited talk · AV4D, ICCV 2023
2021–present
This direction develops useful audio-visual representations while controlling the cost of perception. Listen to the Pixels (ICIP 2021) learns joint segmentation from correspondences between sound and vision. AudViSum (BMVC 2021) uses self-supervised reinforcement learning to produce diverse audio-visual summaries. EgoAdapt (ICCV 2025) brings this strand to efficient egocentric perception through adaptive cross-modal distillation and policy learning, covering action recognition, active-speaker localization, and behavior anticipation. This interest in selecting useful information also connects to my newer work on efficient reasoning.
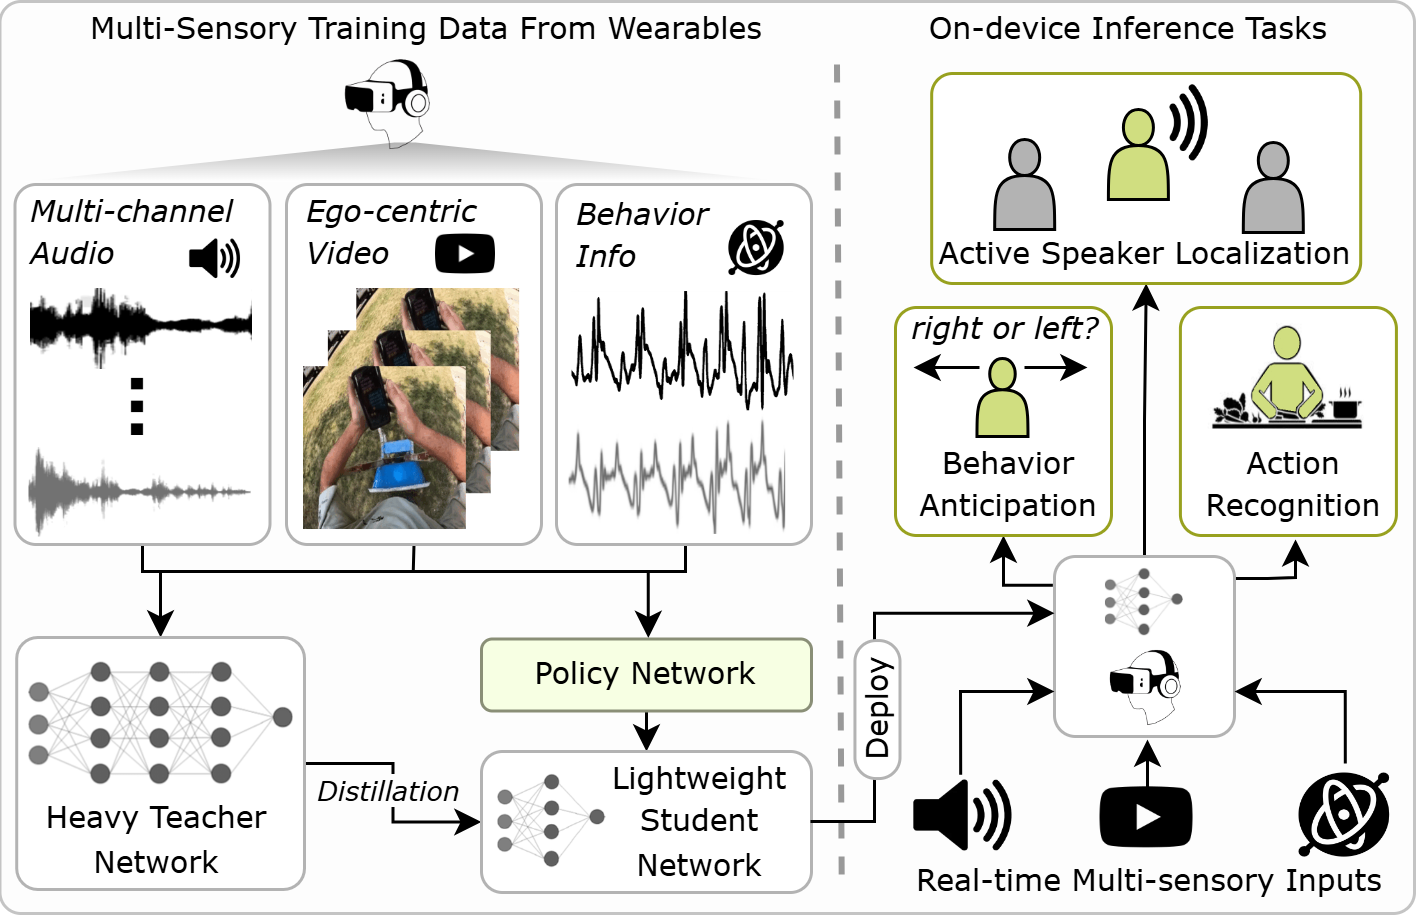
Adaptive multisensory distillation and policy learning for efficient egocentric perception.
Presentations: Oral presentation · BinEgo-360°, ICCV 2025 Invited talk · NYC Computer Vision Day, NYU 2025
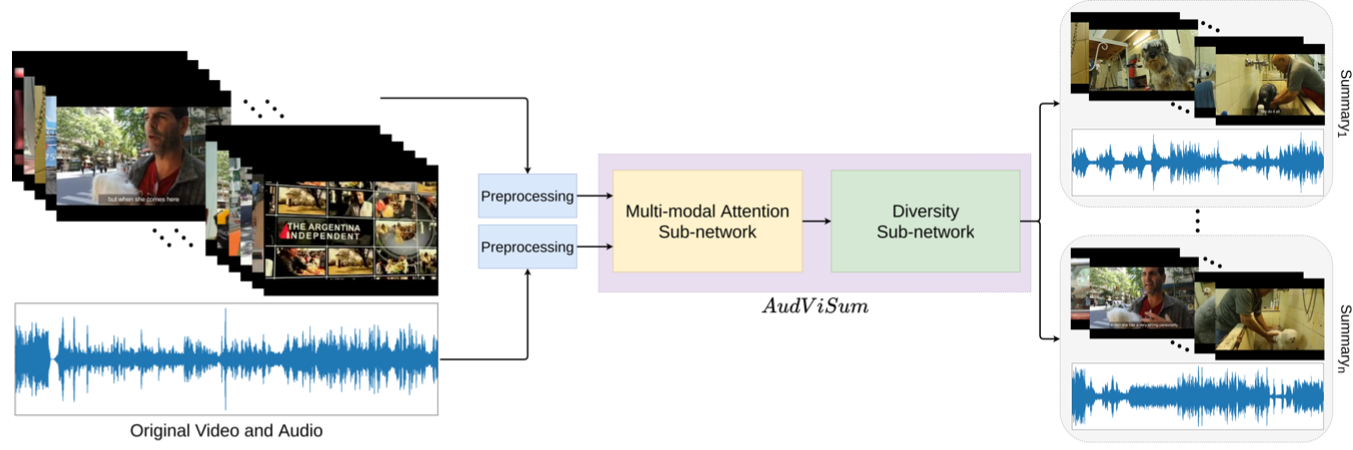
Self-supervised reinforcement learning for diverse, informative audio-visual summaries.
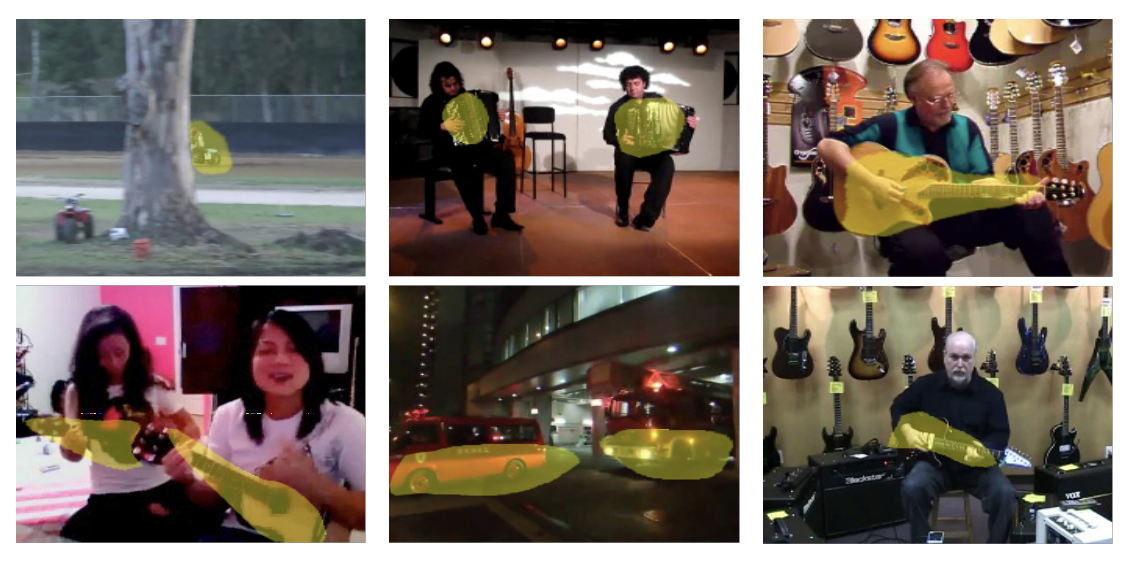
Self-supervised joint audio-visual segmentation by exploiting correspondence between the modalities.
2024–present
I build and evaluate models that jointly ground sound, video, and language. Meerkat (ECCV 2024) addresses fine-grained grounding in space and time. AURELIA (ICCV 2025) improves structured reasoning at test time, while AVTrustBench (ICCV 2025) examines robustness and reliability. AURA separates perceptual grounding from the validity of reasoning steps, revealing gaps that answer accuracy can miss. AMUSE (CVPR 2026) extends the direction to multi-speaker interactions: identifying who speaks, tracking roles and events, and evaluating agentic understanding, with RAFT for data-efficient alignment.
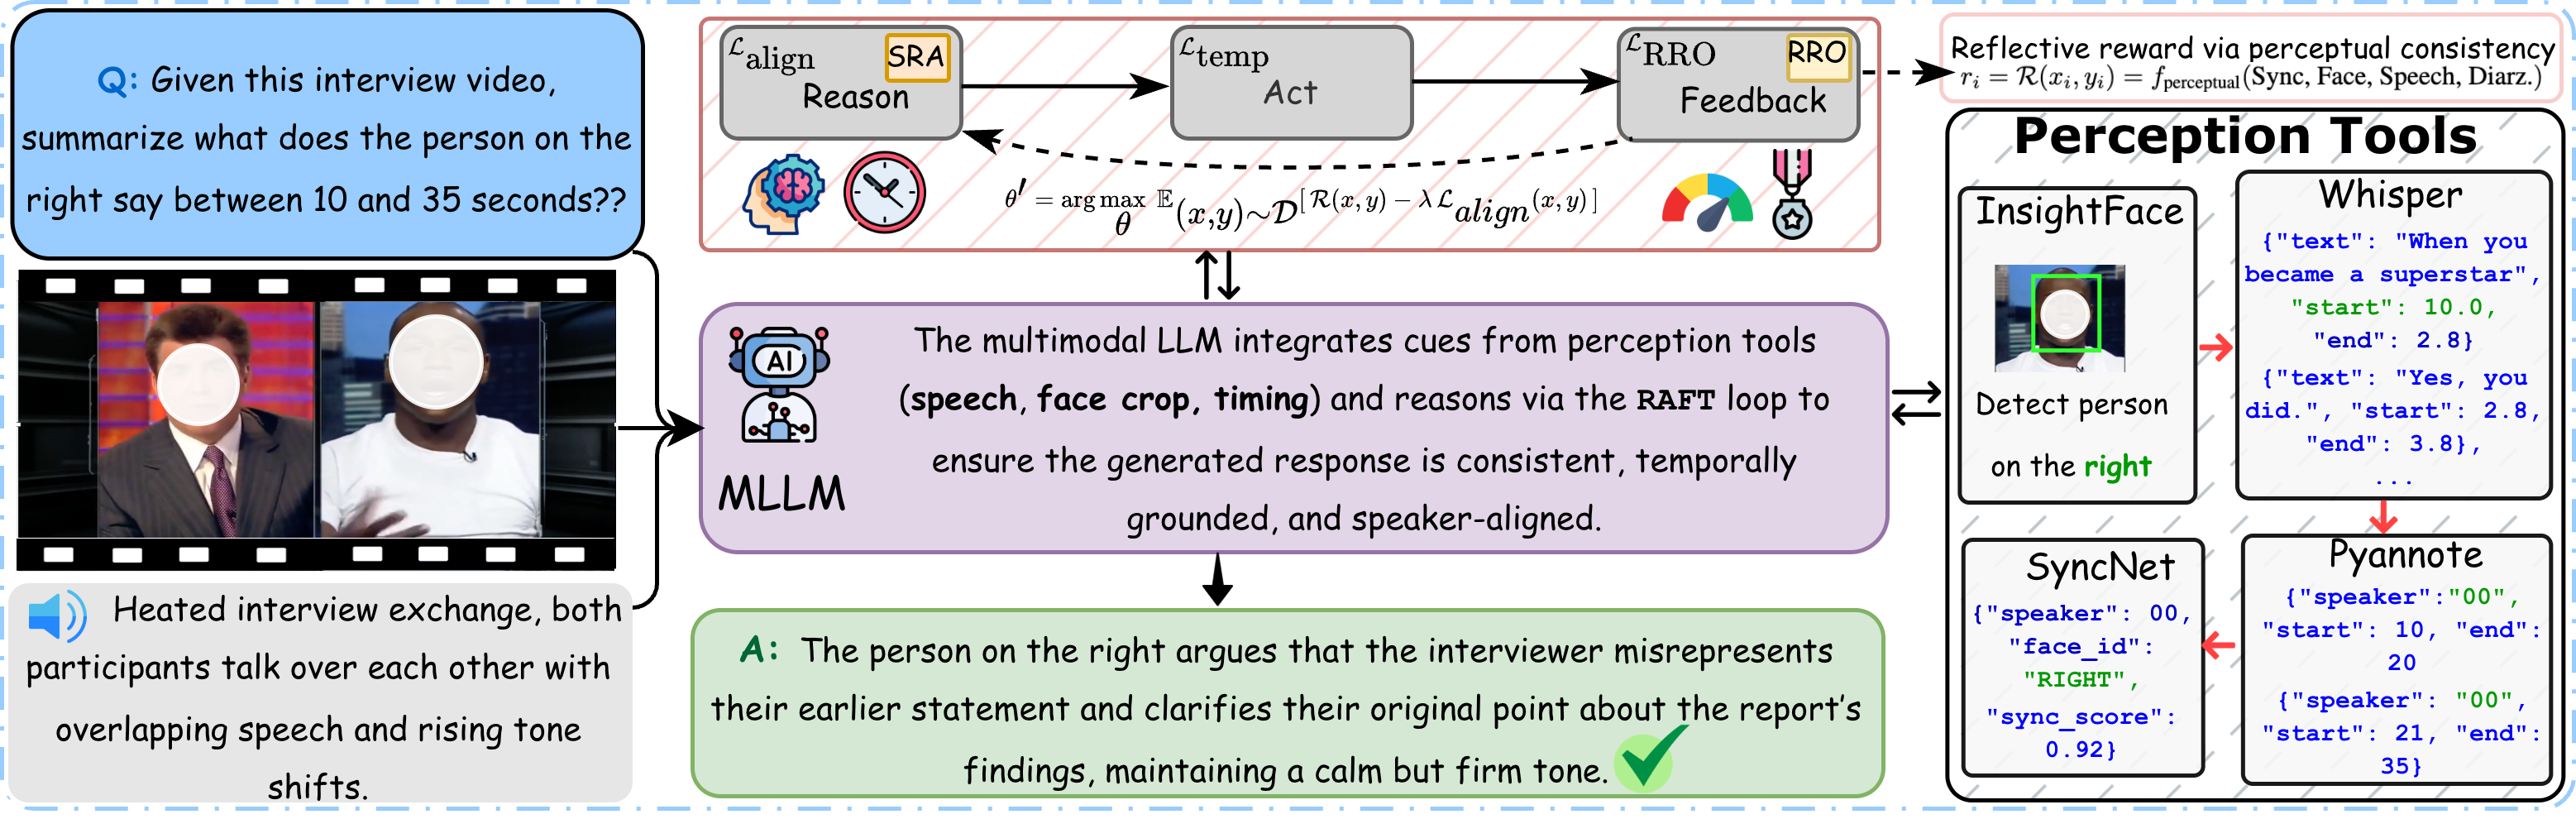
A benchmark for agentic multi-speaker understanding, paired with the RAFT alignment framework.
Presentations: Research presentation · Apple booth, CVPR 2026
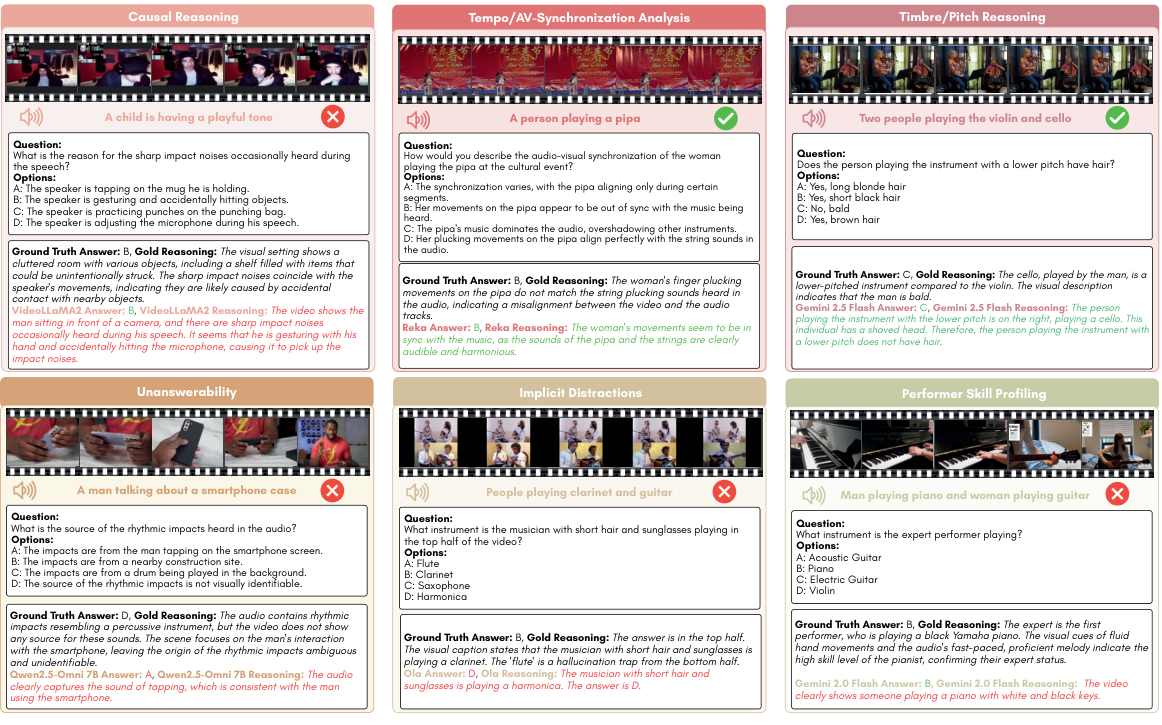
Evaluating audio-visual reasoning traces by separating factual consistency from the validity of core inferences.
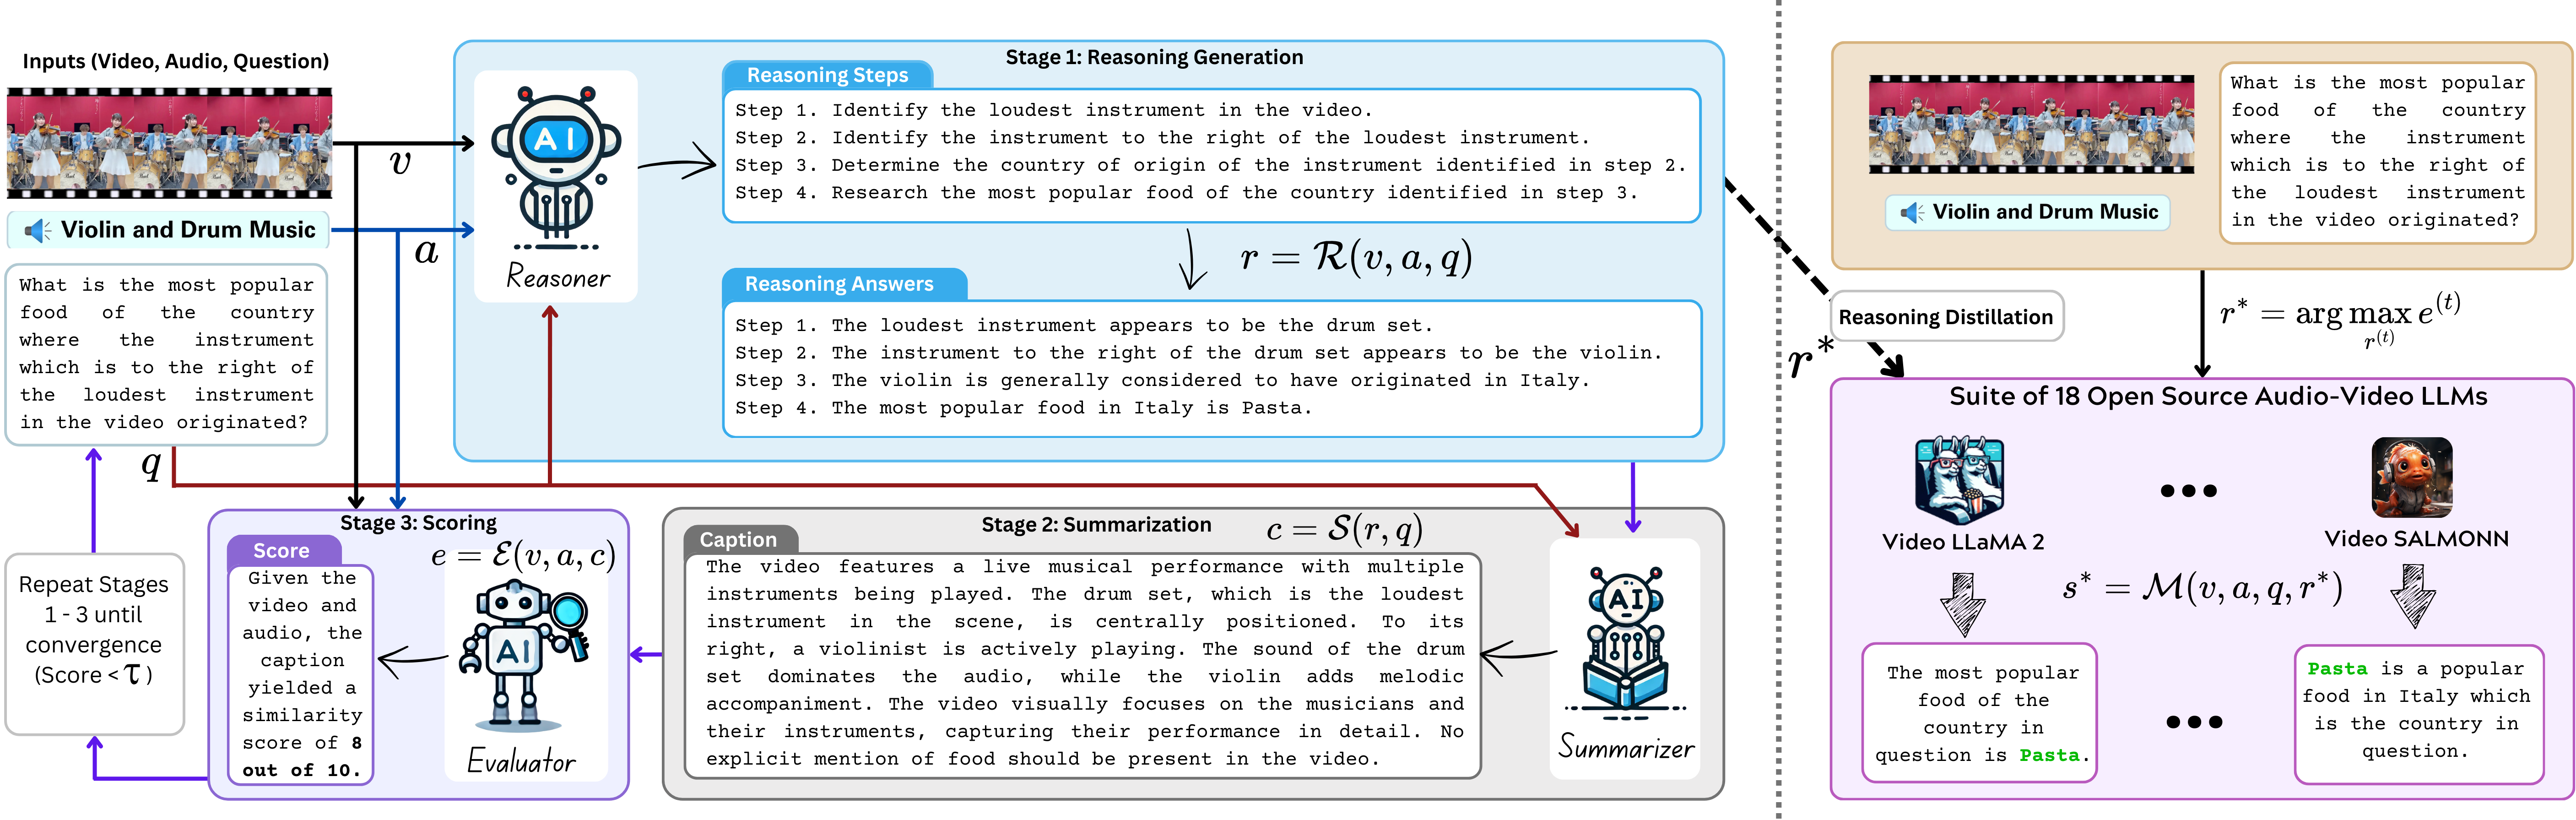
An actor–critic framework for structured audio-visual reasoning at test time, alongside AVReasonBench.
Presentations: Invited presentation · CLVL, ICCV 2025 Invited presentation · AVGenL, ICCV 2025
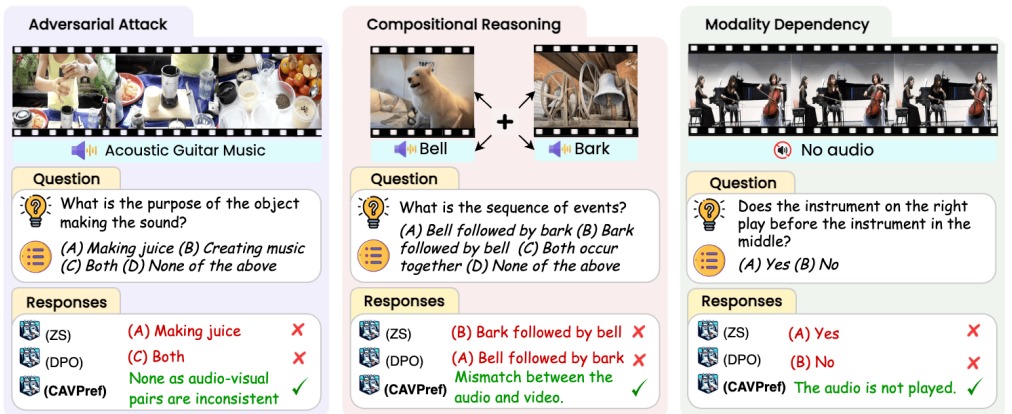
Evaluating audio-visual reliability under adversarial attacks, compositional reasoning, and modality-specific dependencies.
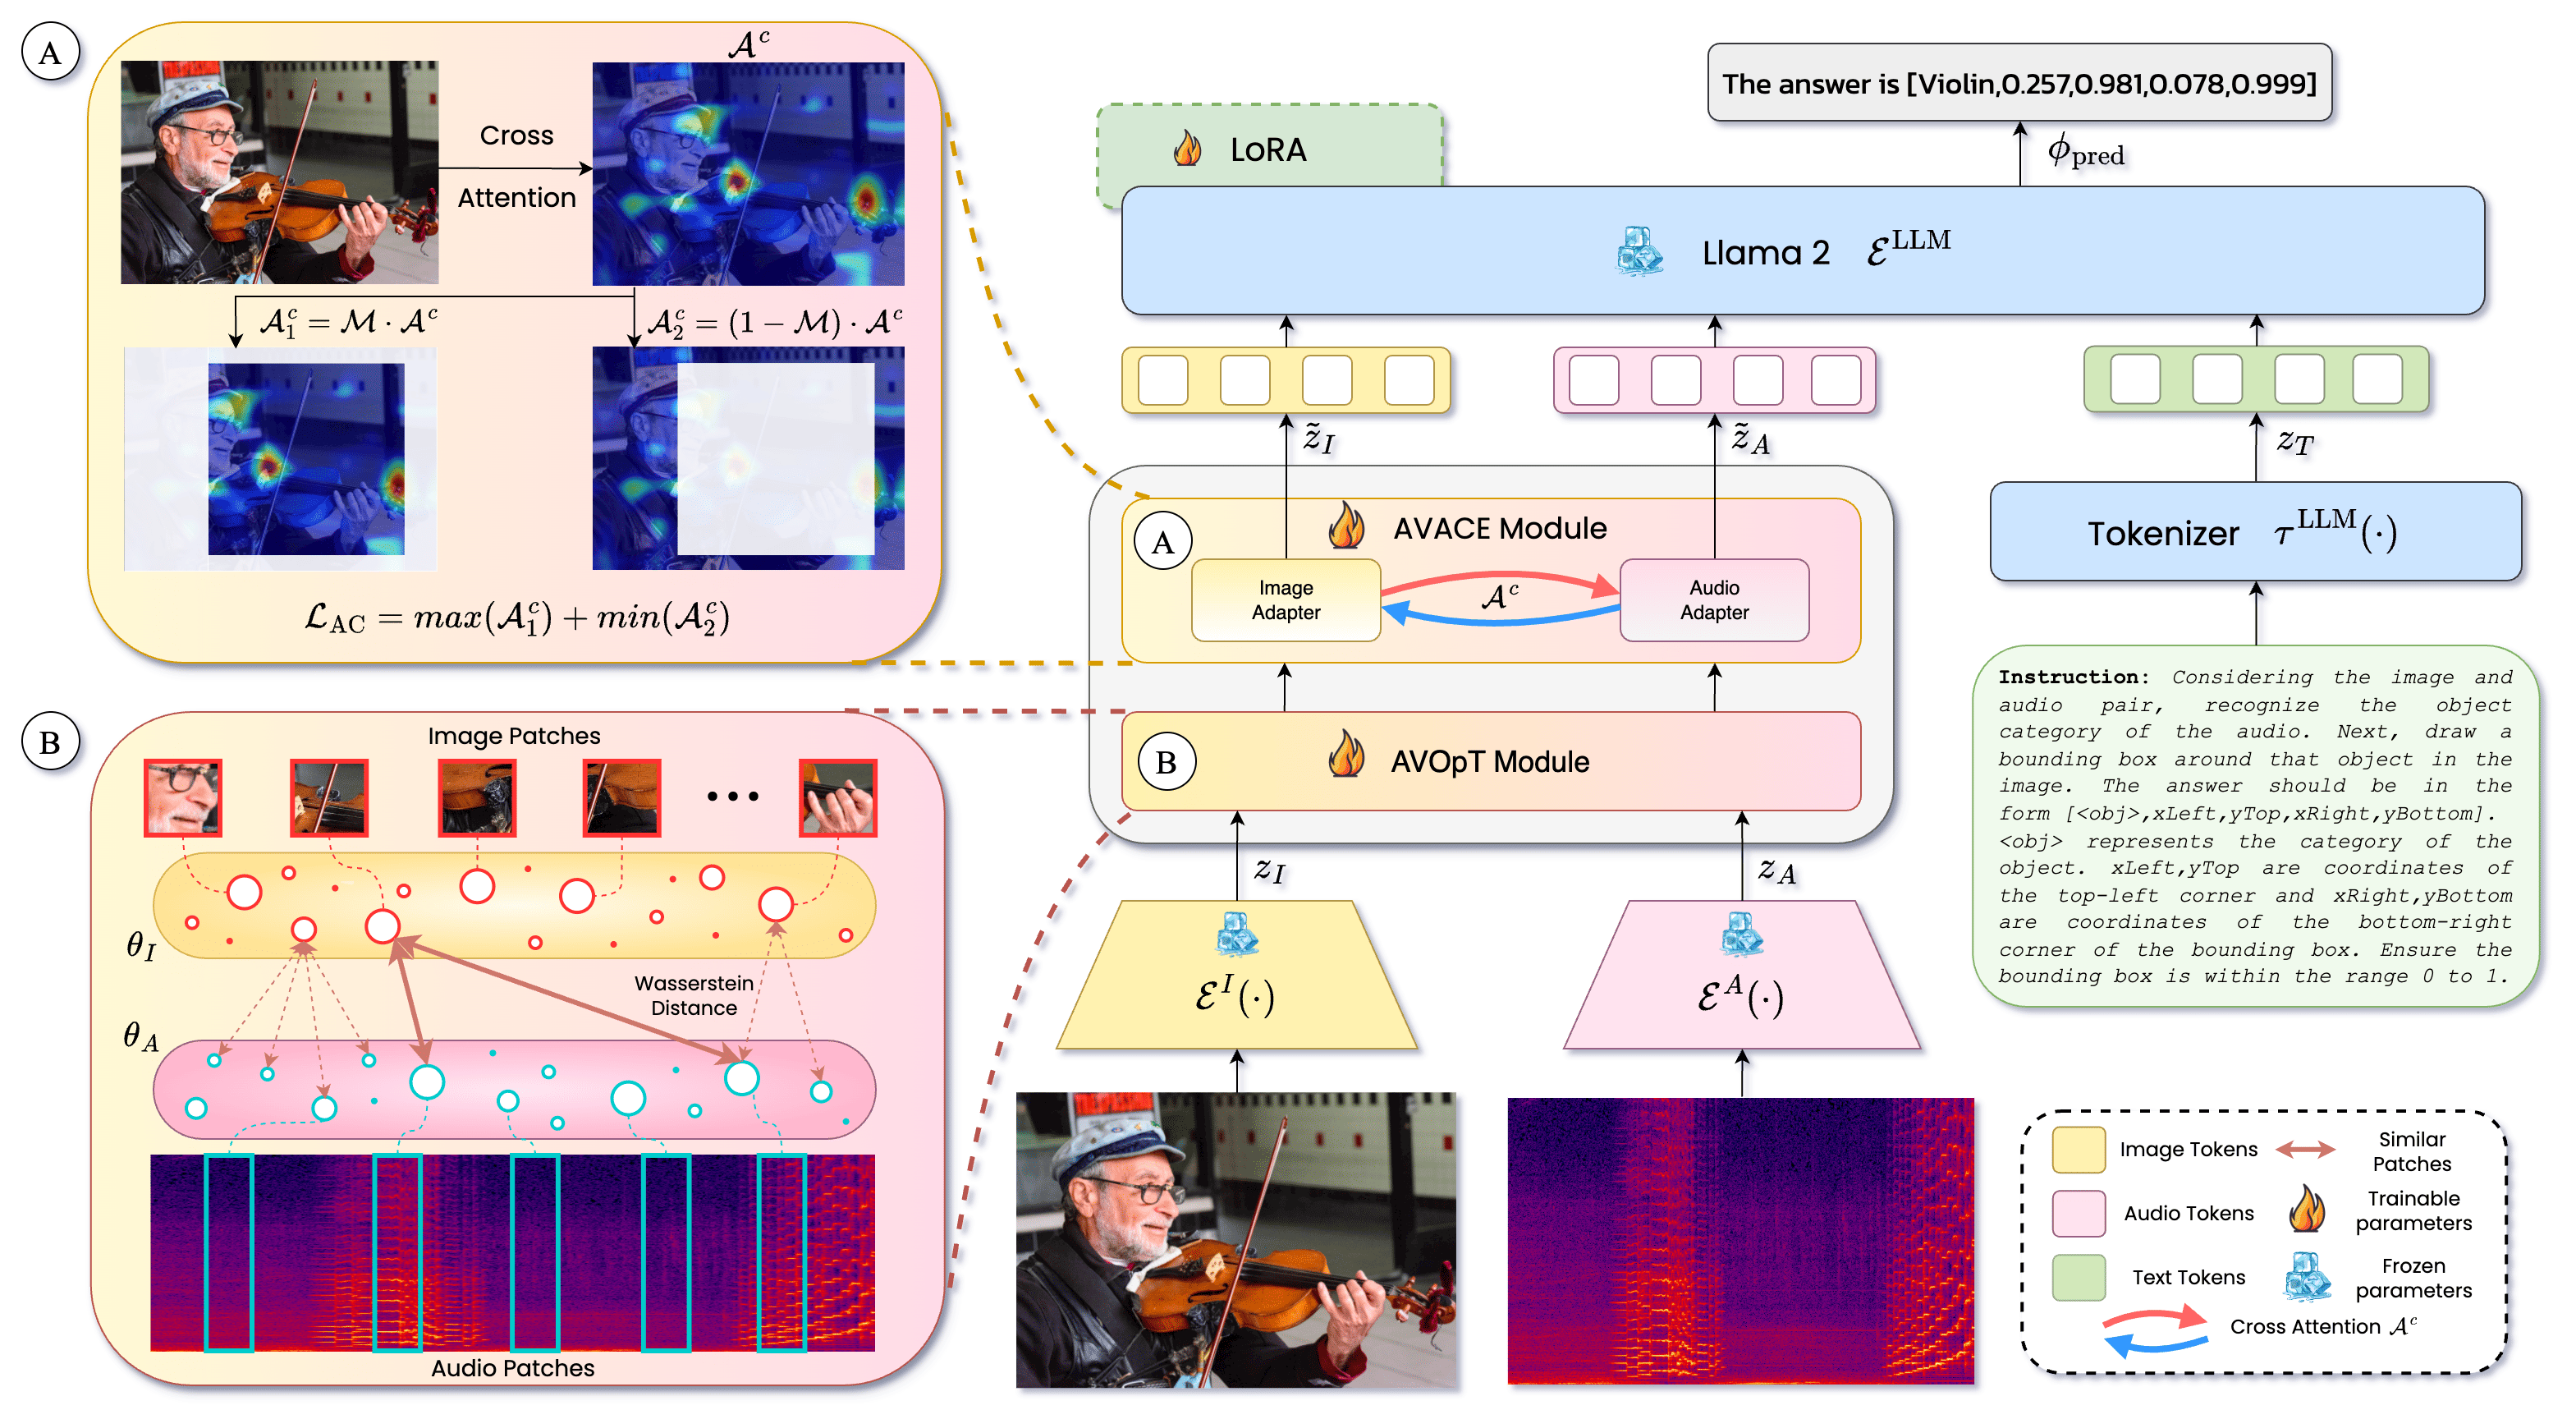
Fine-grained audio-visual grounding in space and time through modality alignment and instruction tuning.
Presentations: Invited talk · AVGenL, ECCV 2024
2022–present
My vision-language work connects robust representation learning to understanding and embodied interaction. APoLLo (EMNLP 2023) combines adapters and prompts for few-shot adaptation. ASPIRE (ACL Findings 2024) uses language-guided augmentation to reduce reliance on spurious visual cues. Wayfinding / VLMNav (NAACL 2024) synthesizes platform-independent navigation instructions through in-context learning. Intent-o-meter (Scientific Reports 2024) combines image, text, and psychological cues to model perceived intent in social media posts. These foundations connect to the newer agentic work on learning, reasoning, and acting across environments.
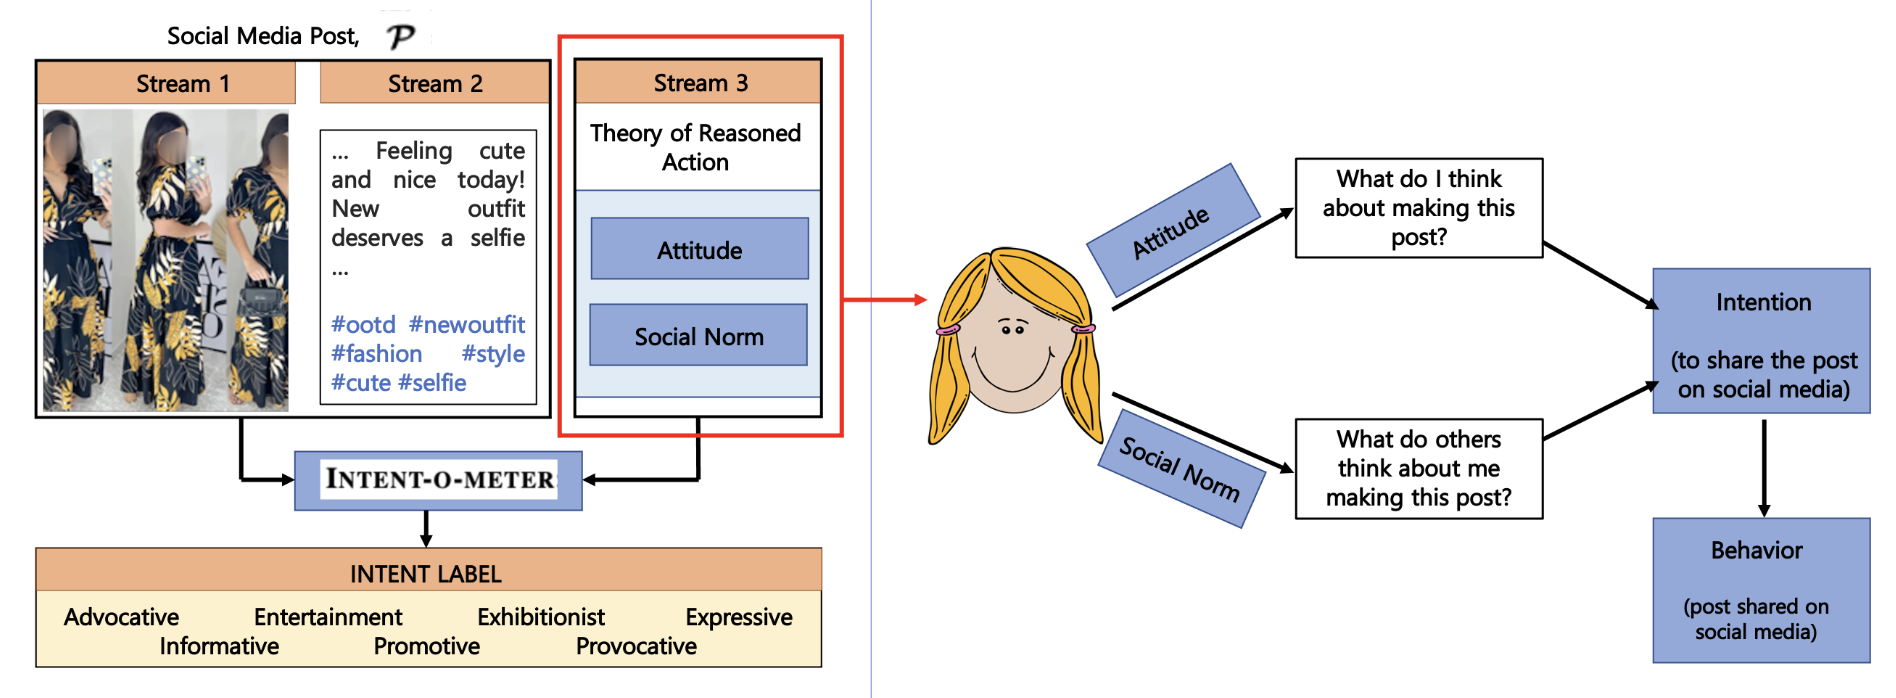
Predicting perceived intent in multimodal social media posts using visual, textual, and psychological cues.
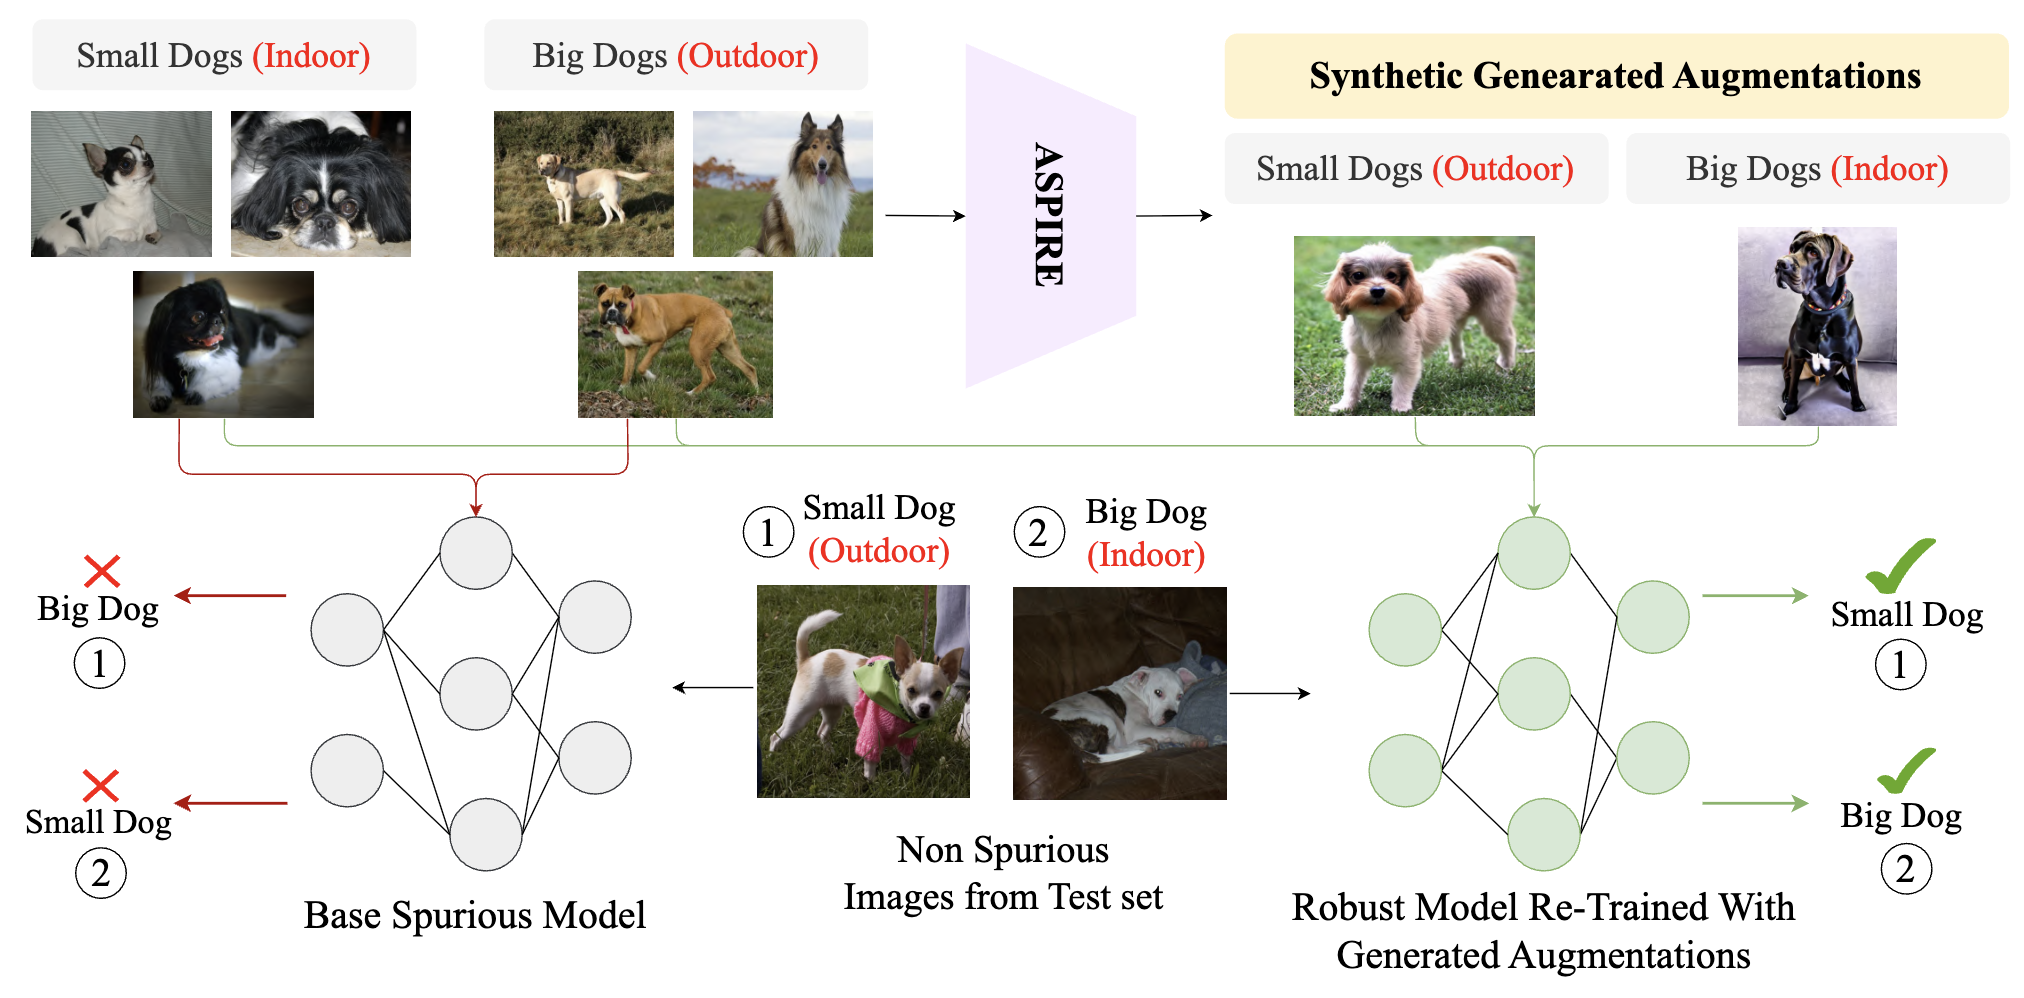
Language-guided image augmentation to reduce dependence on spurious visual features.
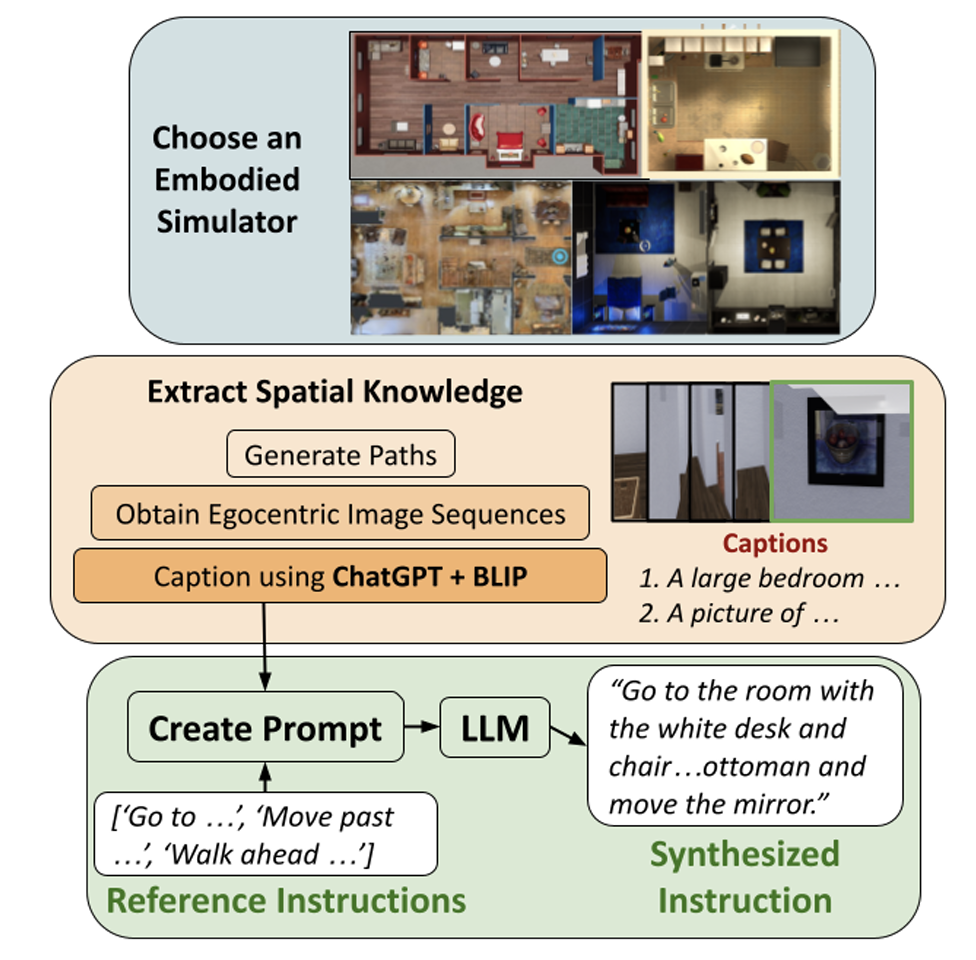
Generating platform-independent wayfinding instructions with in-context learning.
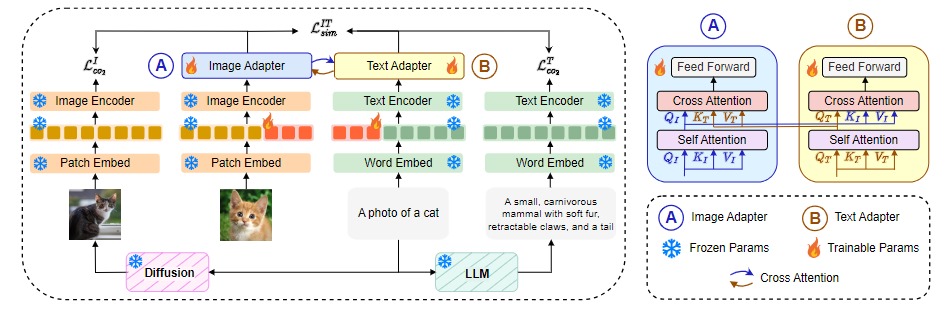
Combining adapters and prompts to improve few-shot generalization in vision-language models.
2021–2023
Earlier work focuses on efficient image restoration and physically grounded evaluation. V-DESIRR (ICCV 2021) is a multi-scale network for single-image reflection removal, addressing weak through strong reflections. Measured Albedo in the Wild (MAW, ICCP 2023) introduces measured-albedo data and complementary metrics for evaluating intrinsic image decomposition. This strand sits alongside my broader work on inverse rendering and video quality assessment, including the video enhancement article linked under Miscellaneous.
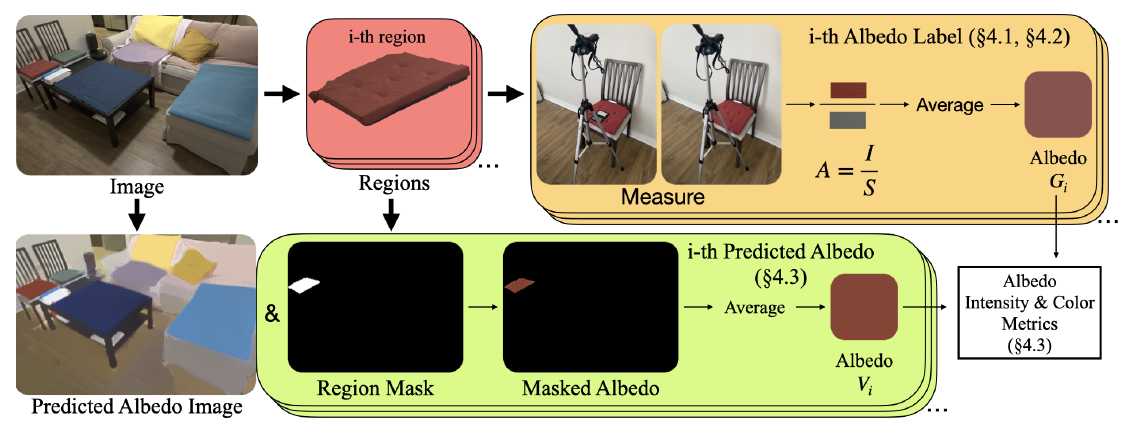
A measured-albedo dataset and evaluation metrics for intrinsic image decomposition.
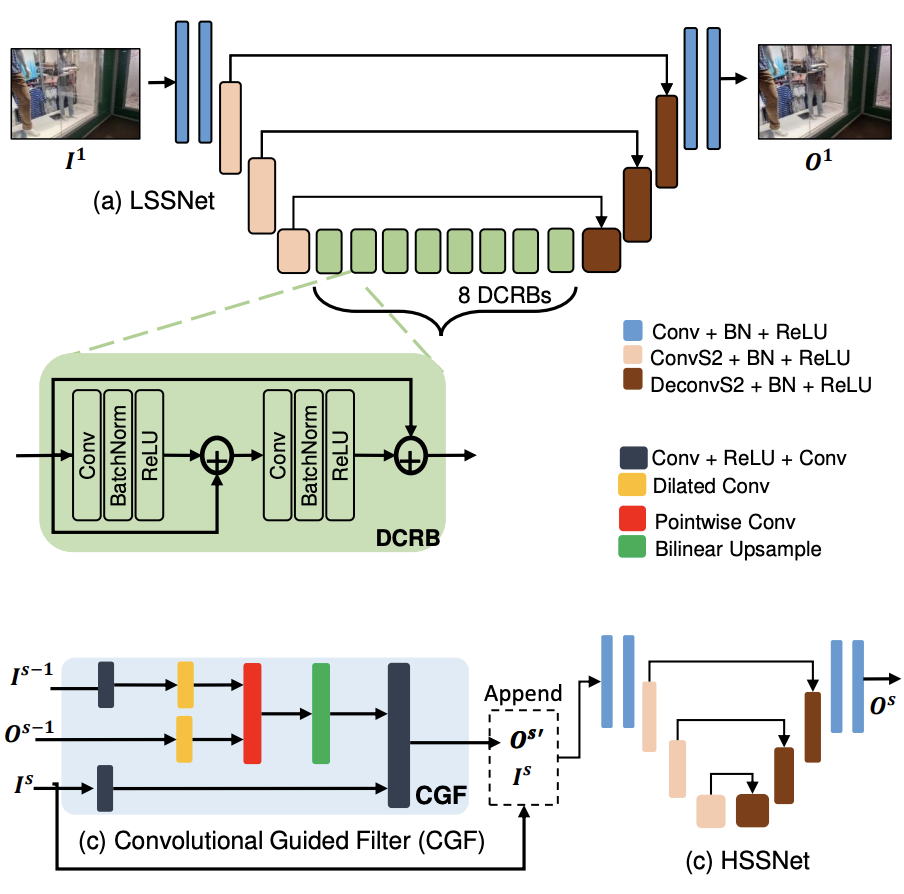
A multi-scale architecture for fast single-image reflection removal.


