 Google Scholar
 GitHub
 LinkedIn
 X
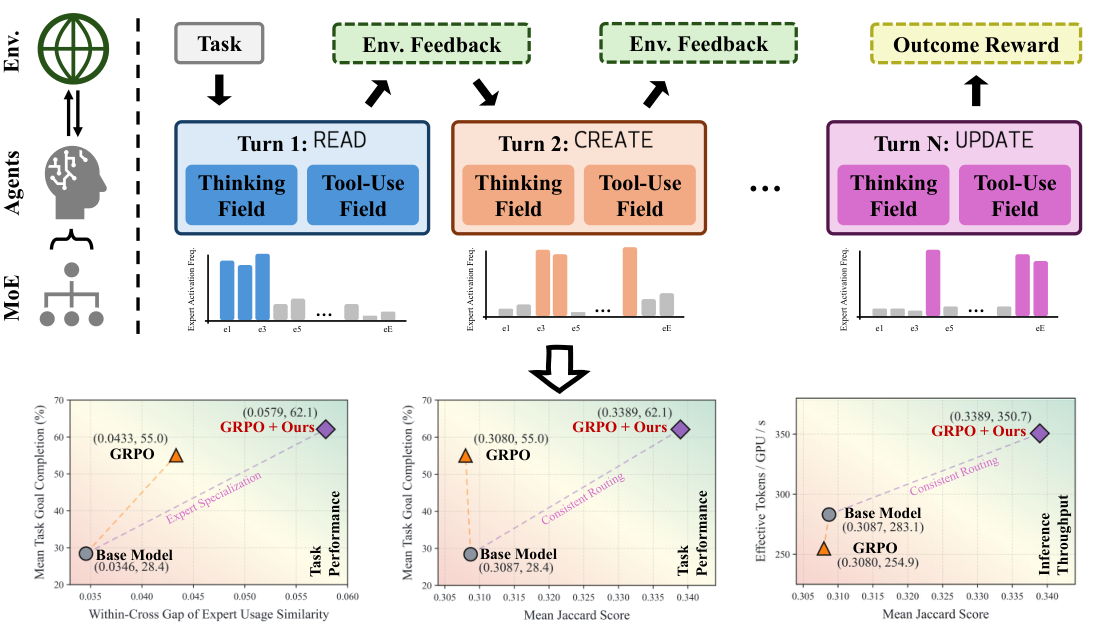
Structuring MoE Expert Selection for Agentic Reinforcement Learning
Aligning mixture-of-experts routing with agent operations through hierarchical control during reinforcement-learning post-training.
Research Scientist at Apple Machine Learning Research
Efficient agents · Reasoning compression · Multimodal learning
firstname_lastname [at] apple [dot] com
Feel free to reach out for research collaborations.
I am a Research Scientist at Apple Machine Learning Research, where I work on efficient on-device tool-calling agents and reasoning compression. My broader research focuses on multimodal foundation models that combine vision, audio, and language for fine-grained perception, grounded reasoning, and cross-modal generation. I am particularly interested in improving their efficiency and reliability through post-training.
I earned my PhD in Computer Science from the University of Maryland, College Park, advised by Prof. Dinesh Manocha, and my MTech in Computer Science & Engineering from IIIT Hyderabad, advised by Prof. C. V. Jawahar.
During my PhD, I worked on audio-visual reasoning and alignment at Apple with Chun-Liang Li and Karren Yang; multisensory egocentric perception at Meta Reality Labs with Ruohan Gao; speech-driven facial synthesis in the Talking Heads team at Google Research with Avisek Lahiri and Vivek Kwatra; and multimodal audio generation at Adobe Research with Joseph K J. I also worked with Mohamed Elhoseiny at KAUST and collaborated with Kristen Grauman and Salman Khan.
Before my PhD, I developed video enhancement algorithms with the Camera and Video AI team at ShareChat and vision systems for consumer devices at Samsung R&D Institute Bangalore. My earlier research included work at ISI Kolkata with Ujjwal Bhattacharya and IIT Kharagpur with Pabitra Mitra.
Aligning mixture-of-experts routing with agent operations through hierarchical control during reinforcement-learning post-training.
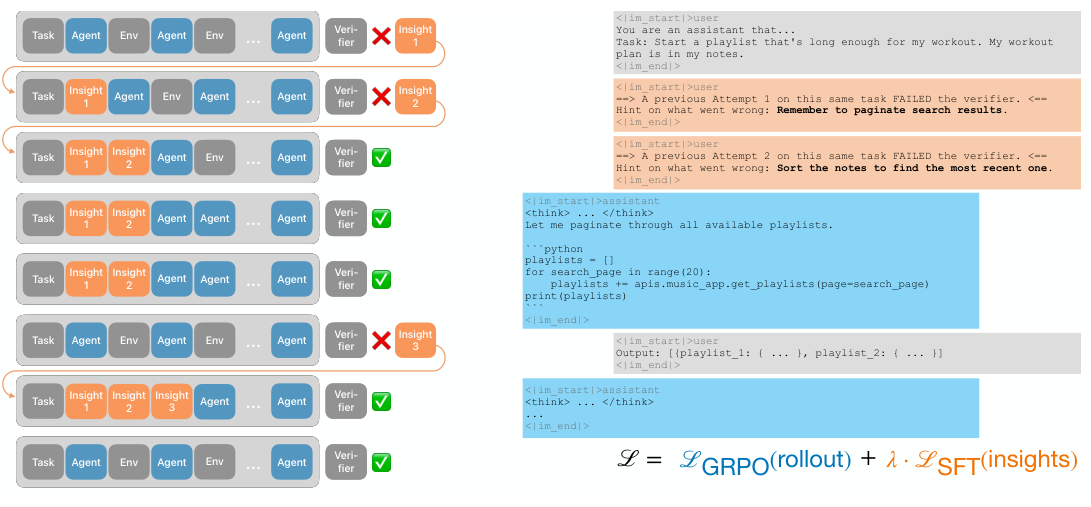
Learning from brief, self-generated insights after failed attempts, then internalizing those insights during training.
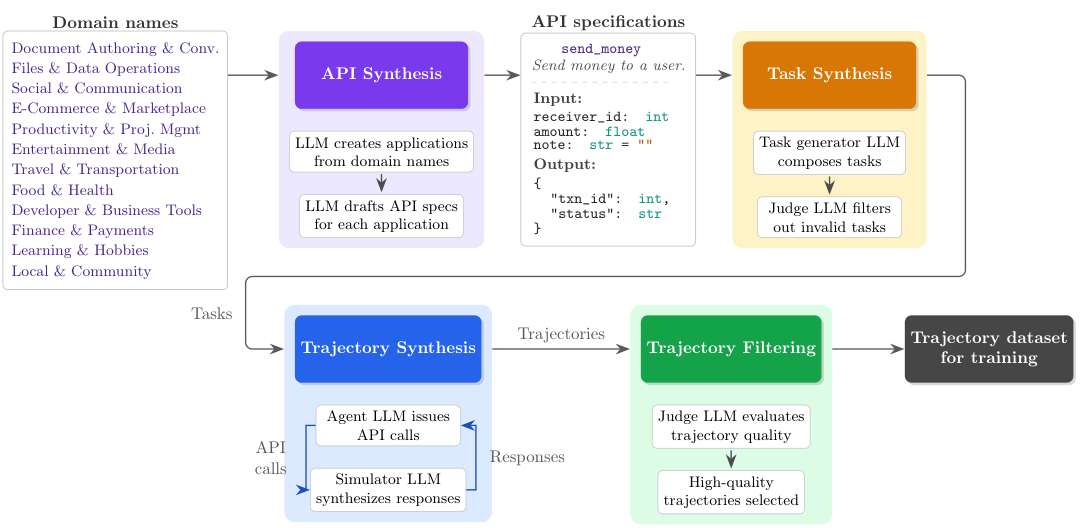
Generating stateful API-calling trajectories with LLM world models to train agents that generalize to unseen environments.
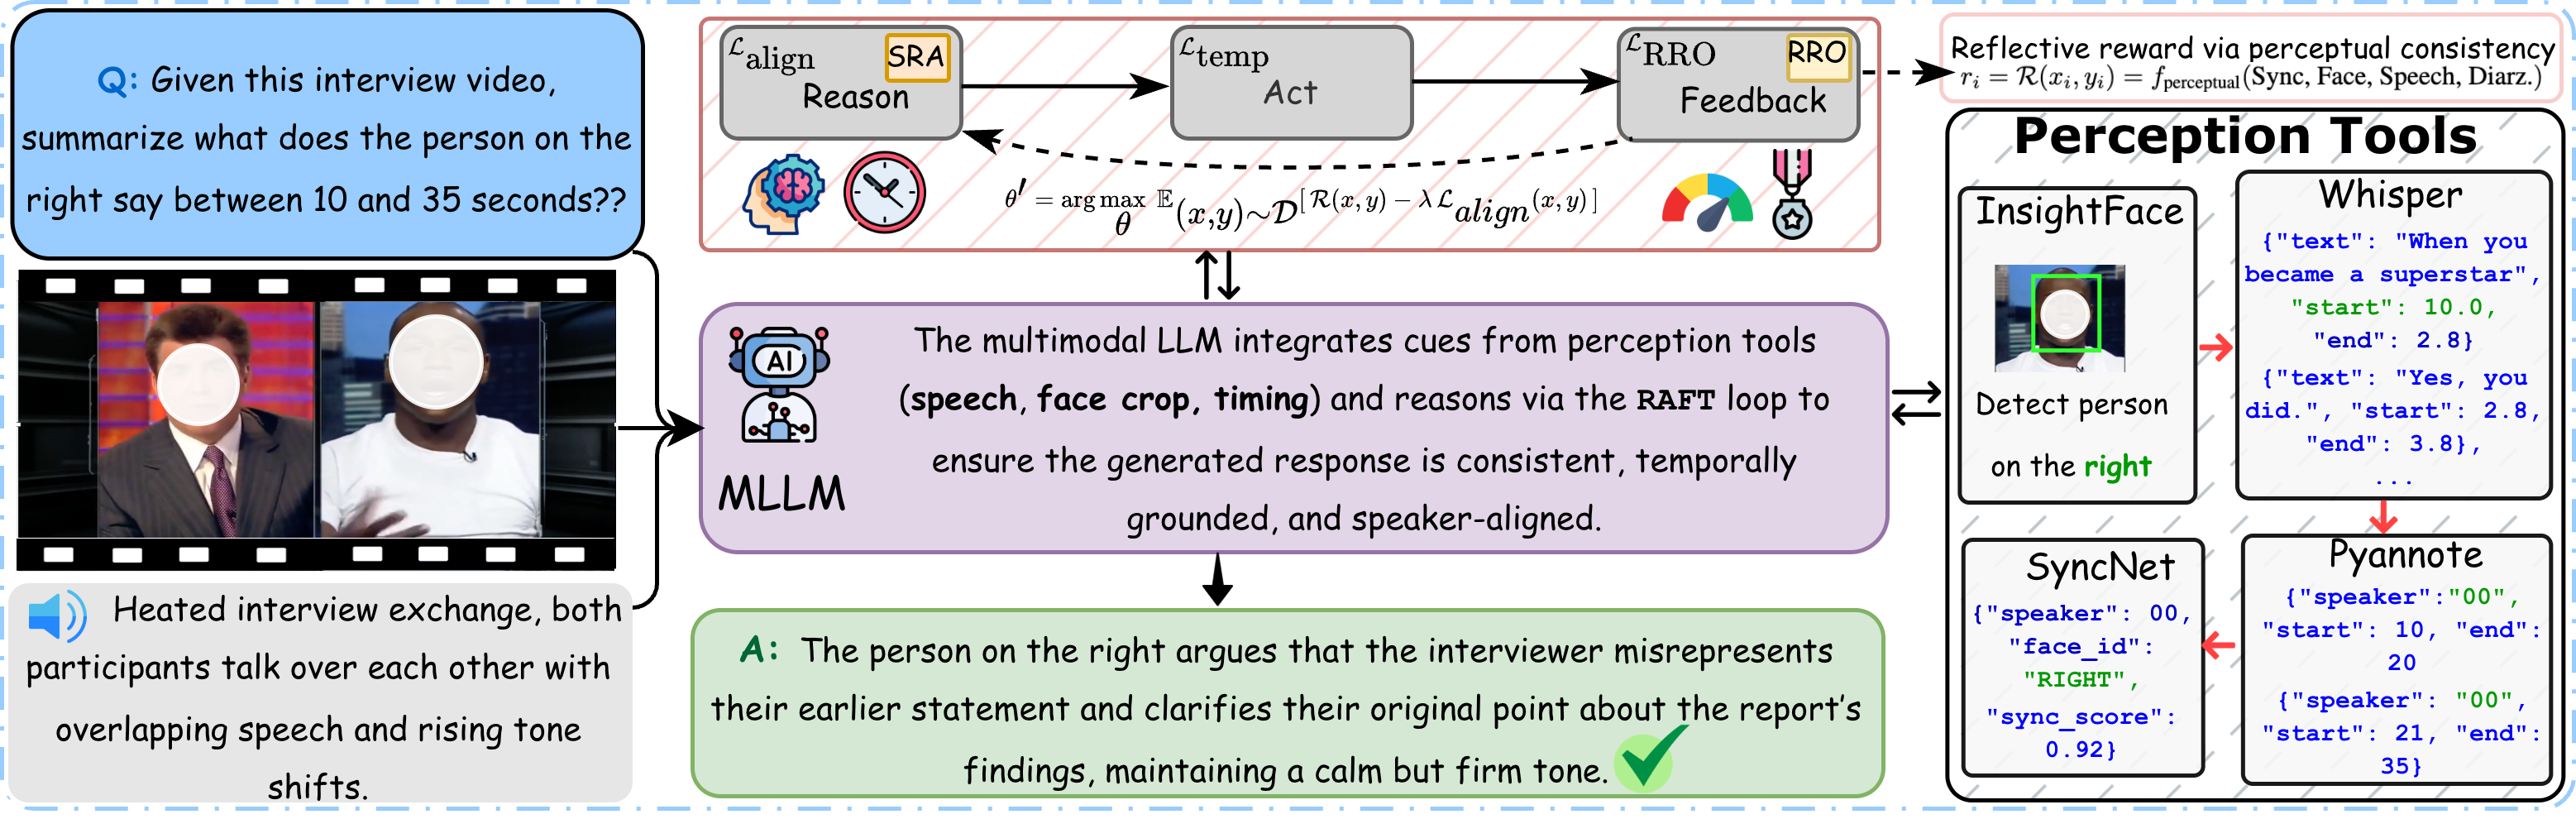
A benchmark for agentic multi-speaker understanding, paired with the RAFT alignment framework.
Presentations: Research presentation · Apple booth, CVPR 2026
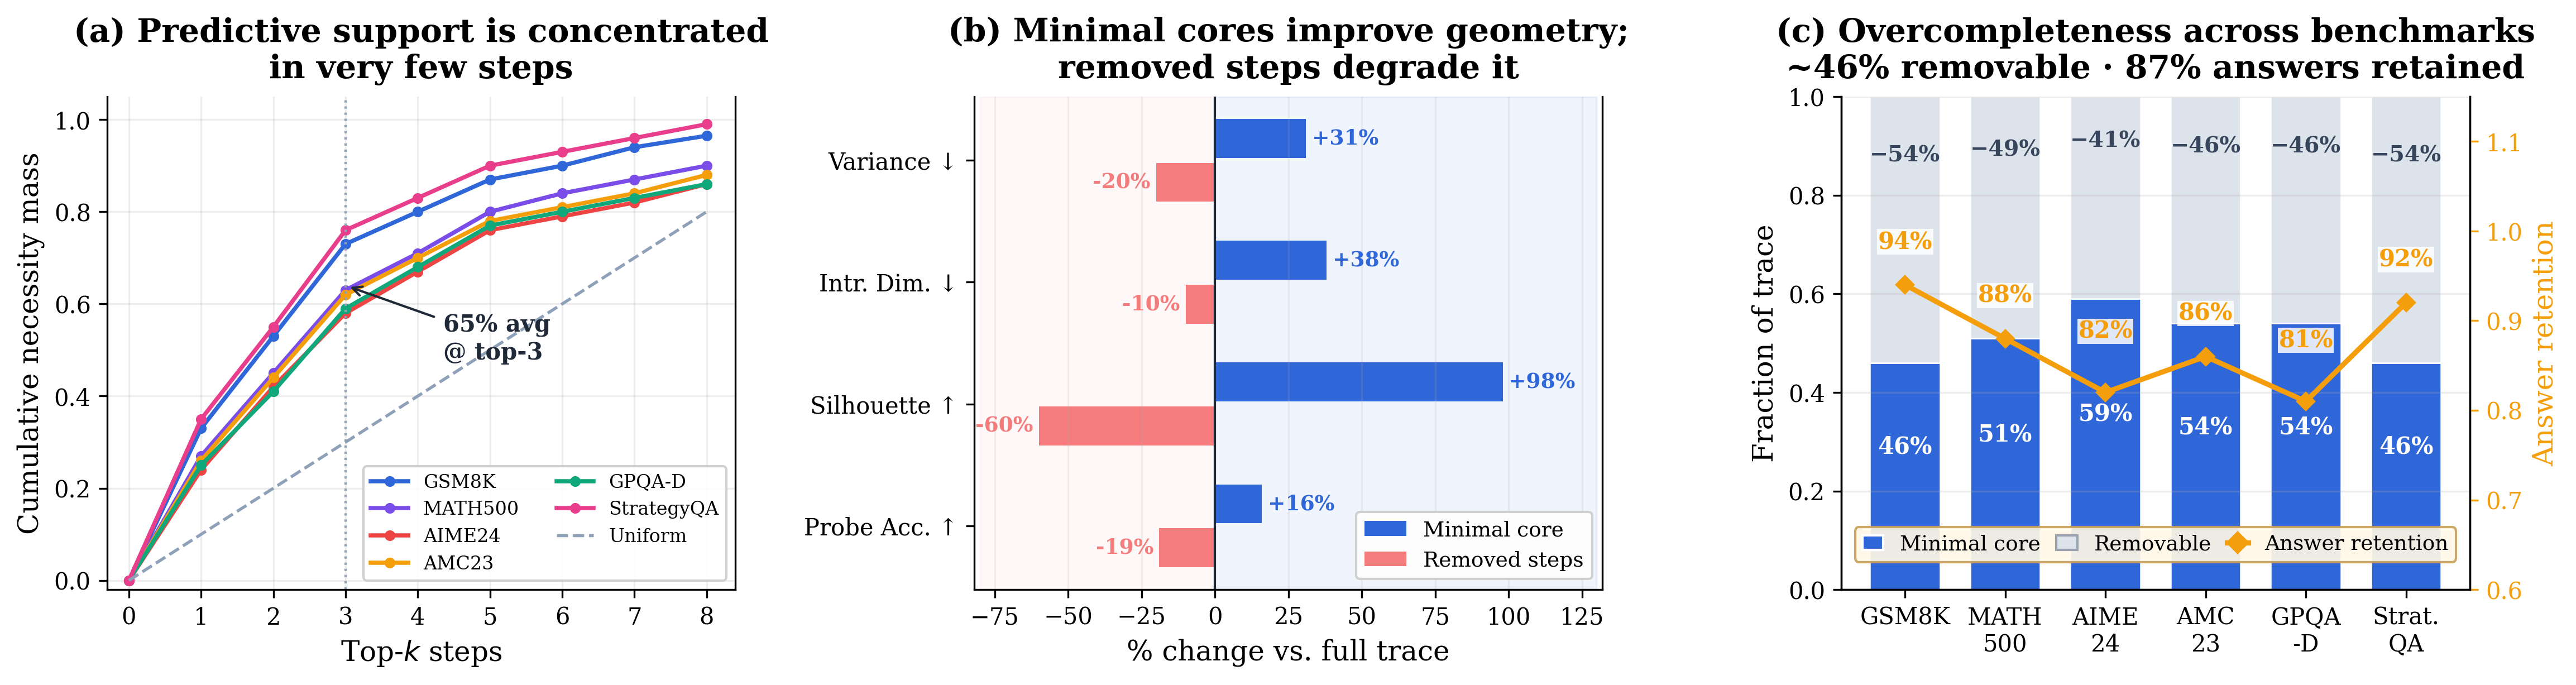
Identifying the compact support within long reasoning traces and studying its representation geometry.
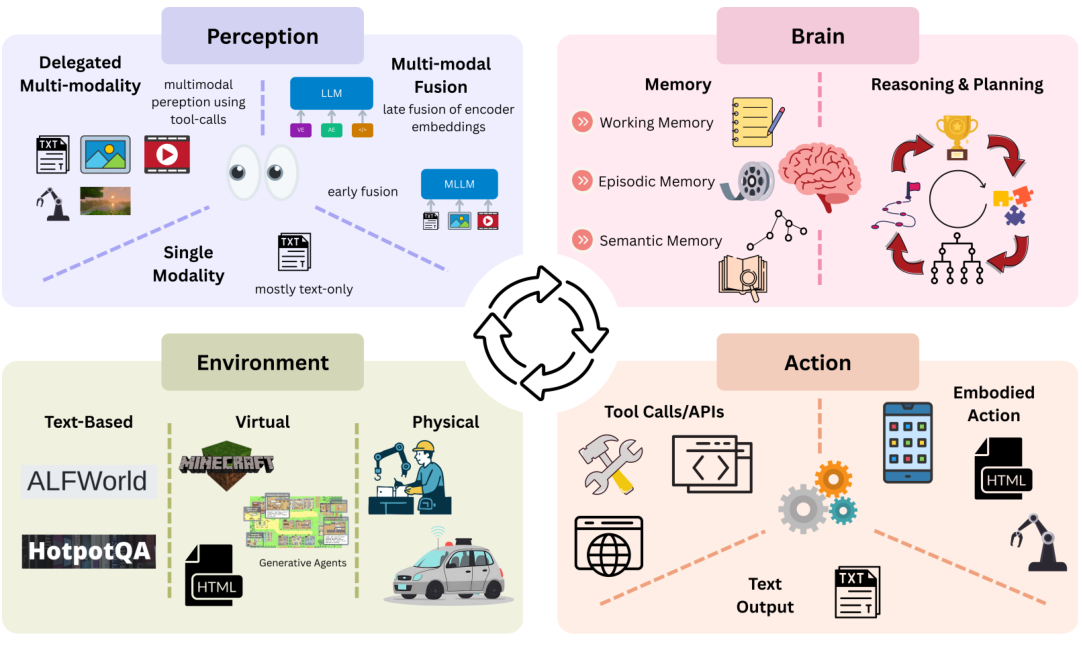
A survey of the techniques, applications, and open challenges in multimodal agentic frameworks.